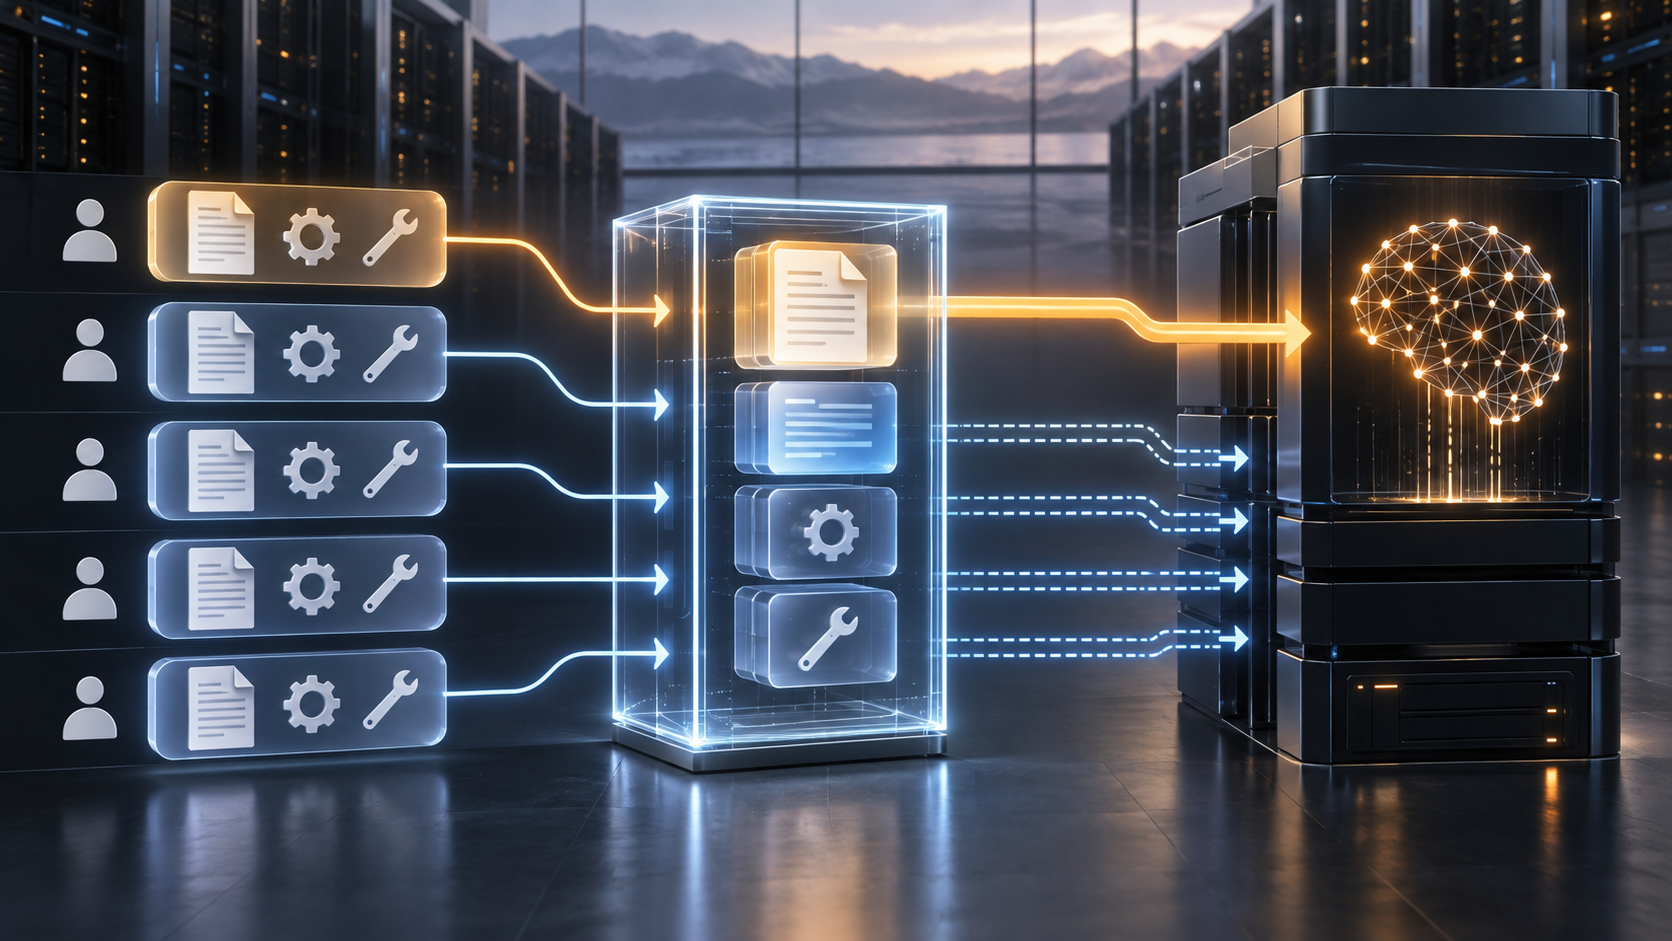
Prompt caching gives operators a way to treat repeated context as reusable infrastructure. The practical opportunity depends on how often requests share the same prefix and produce cache hits, so implementation choices and workload measurement remain central.
What the evidence says
AWS Machine Learning describes six prompt-caching scenarios that use the Amazon Bedrock Converse API and progress from basic to advanced patterns. One scenario caches long documents for repeated analysis questions.
The source explains that prompt caching stores a snapshot of partially processed input. When later requests use the same prefix, Amazon Bedrock can skip redundant computation by reading cached tokens instead of processing those tokens again. Cacheable context can include system prompts, documents, and tool definitions.
For cache hits, the source says this mechanism can reduce time to first token and lower the cost of cached input tokens by as much as 90 percent. It also states that these benefits do not require changing the model or reducing prompt quality. The figure is an upper-bound claim from the provider’s primary account, rather than a guaranteed result for every workload.
Operator implications
Operator analysis: the first task is to identify context that stays stable across multiple requests. Long reference material, recurring system instructions, and repeated tool definitions are candidates because the source explicitly identifies these input types as cacheable.
The cache boundary becomes an operating decision. A request pattern with a shared prefix creates the possibility of reuse; a pattern that frequently changes provides less opportunity for subsequent requests to read cached tokens. Operators should therefore evaluate prompt structure alongside the application’s actual repetition patterns.
Measurement should focus on whether requests produce cache hits and whether those hits correspond with changes in time to first token and cached-input cost. The provider’s maximum claim should serve as a reference point, while observed workload results should determine the practical value. The six scenarios also suggest a staged path: begin with a clear repeated context pattern, observe the result, and then consider more advanced uses.
Limits and open questions
This briefing relies on a single primary account that is not independently confirmed. The evidence establishes the described mechanism, supported context types, six-scenario structure, and an up-to-90-percent claim for cached input tokens on cache hits.
It remains unknown how often a particular production workload would generate cache hits, what latency or cost change it would realize, and how results vary across request patterns. The evidence pack also does not provide independent benchmarks, customer outcomes, or scenario-level performance measurements. Operators therefore need workload-specific observation before drawing conclusions about realized impact.