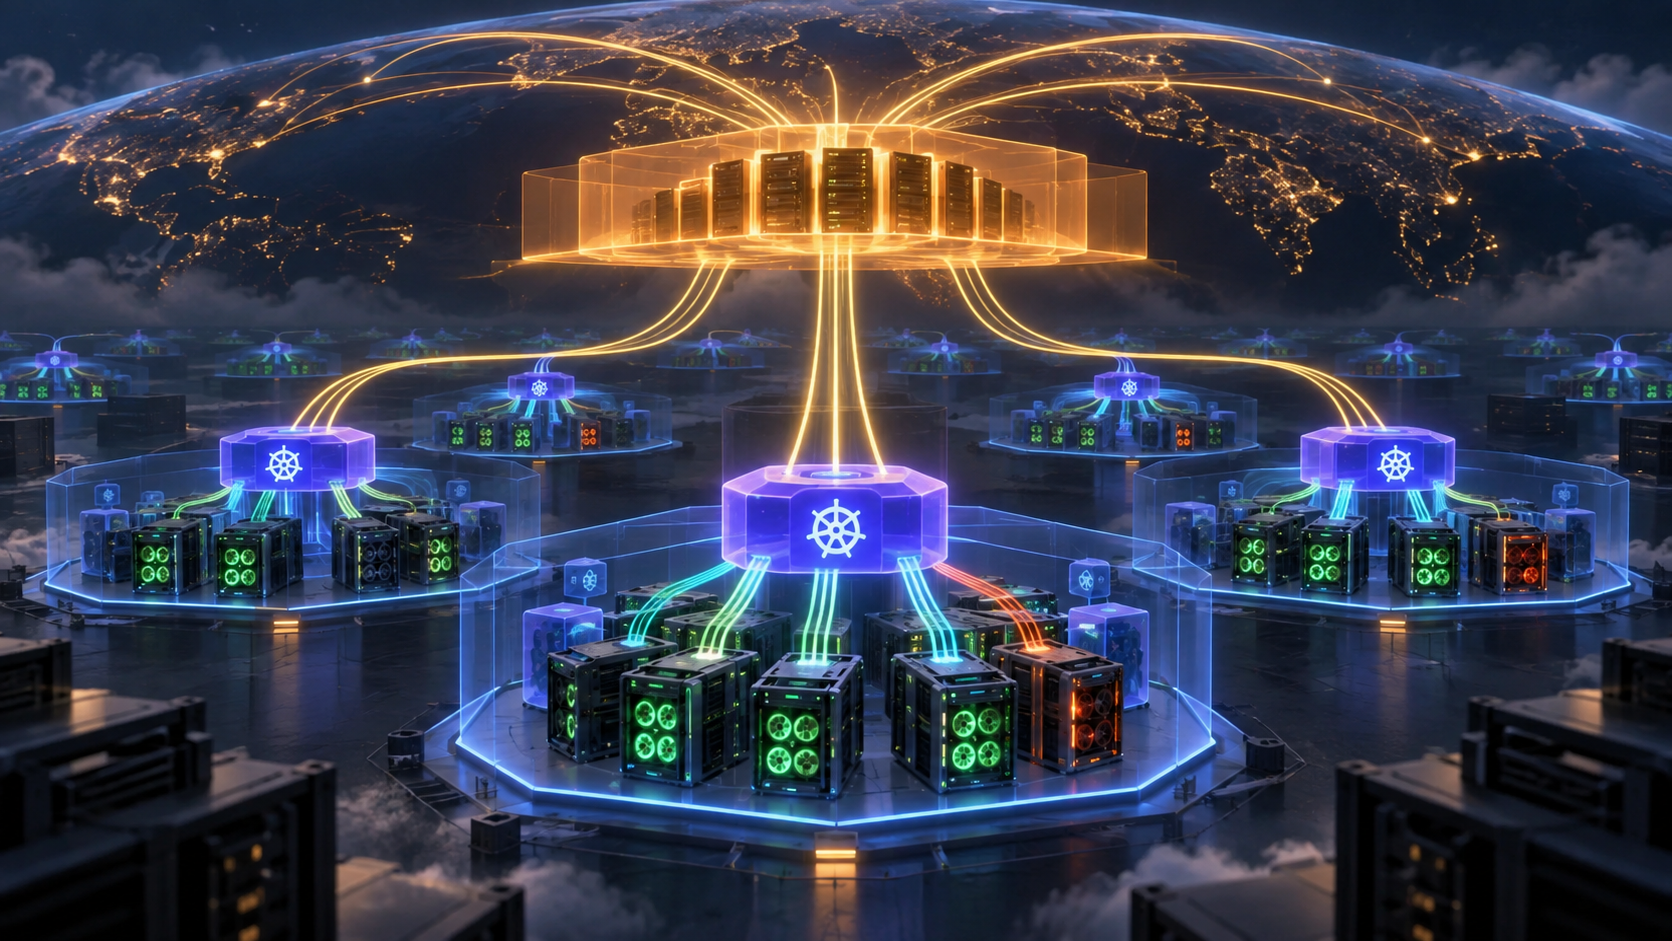
Inference routing is being positioned as part of the cluster environment around GPU-backed workloads. SageMaker HyperPod Inference Gateway is presented as a Kubernetes-native, GPU-aware routing system for existing HyperPod infrastructure, with reducing GPU waste as a stated aim.
What the evidence says
AWS Machine Learning has announced SageMaker HyperPod Inference Gateway as a single EKS managed add-on. The supplied account describes a two-tier architecture built with Kubernetes-native primitives.
Its disclosed first tier is a per-cluster gateway installed directly on each HyperPod/EKS cluster through the `amazon-sagemaker-hyperpod-inference` add-on. The account identifies the system as GPU-aware routing, linking request handling to the infrastructure where GPU-backed inference runs.
The source also gives one chatbot example: time to first token moved from 4.4 seconds to under 800 milliseconds. This is a reported vendor result, not a general performance conclusion.
Operator implications
For teams using HyperPod with EKS, the gateway’s placement inside the cluster environment makes routing an infrastructure concern alongside the existing deployment surface. The two-tier design makes the per-cluster component a tangible point for evaluating rollout, monitoring, ownership, and failure handling.
The stated focus on GPU awareness and reducing GPU waste also puts utilization and request latency in the same operational frame. The reported chatbot result is most useful as a workload-specific benchmark to test in a comparable environment, rather than as a result that can be assumed across deployments.
Evaluation can focus on the visible cluster-level tier: how it fits existing controls, how routing behavior appears in operational monitoring, and whether the deployment model suits current HyperPod/EKS responsibilities. Those are implementation questions prompted by the announced architecture, not results established by the supplied account.
Limits and open questions
This account is not independently confirmed. The evidence establishes that the gateway was announced, is described as Kubernetes-native and GPU-aware, deploys as a single EKS managed add-on on existing HyperPod infrastructure, and uses a two-tier design with a per-cluster first tier.
The source does not establish the test conditions, workload profile, configuration, reproducibility, or broader applicability of the chatbot latency example. It also does not establish the mechanics of the second tier, routing-policy details, operational overhead, failure behavior, compatibility boundaries, or outcomes in independently run environments. Those gaps limit conclusions about general efficiency or performance.