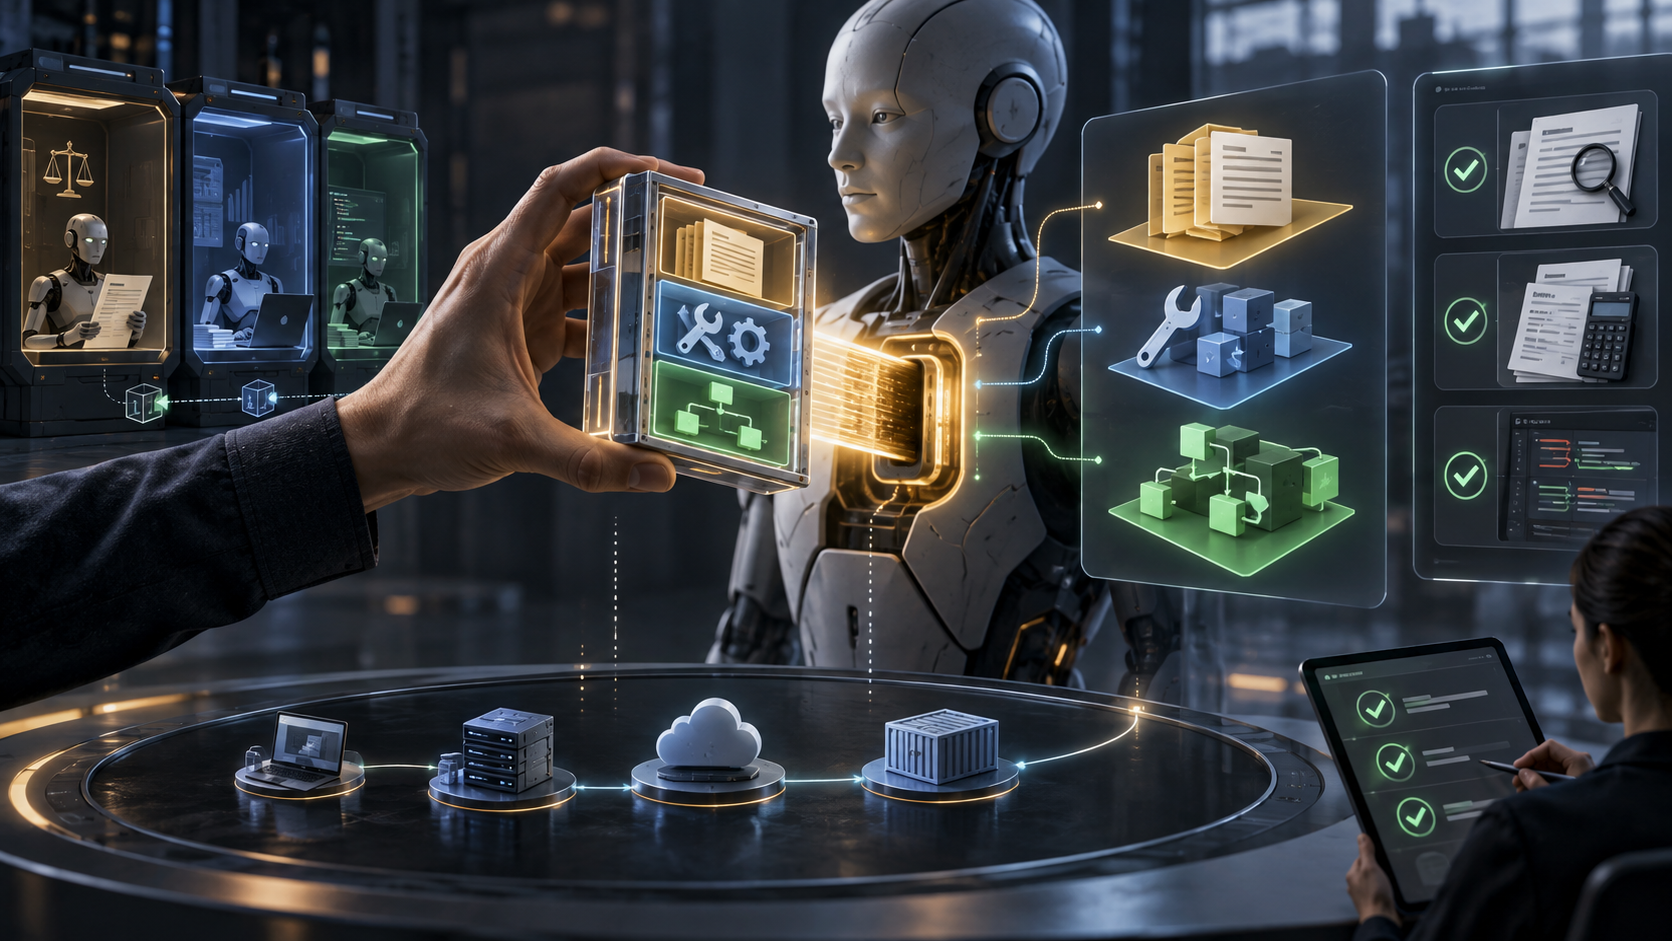
Skill-equipped agents offer a modular approach to domain work: procedures can be packaged separately from an agent’s core instructions and introduced when the relevant task arises. The primary account presents this structure as a way to combine specialized guidance, required tool connections, and step-by-step logic. For operators, the important question is not merely whether a skill exists, but whether its complete behavior can be evaluated within the environment where it will run.
What the evidence says
AWS Machine Learning describes a skill as a reusable instruction set, commonly kept in a SKILL.md file, that teaches an agent a domain-specific task. The cited examples include contract redaction, invoice reconciliation, and adherence to a team’s pull-request conventions.
The account says skills follow the open Agent Skills standard and can move among compatible harnesses. It also states that an agent can load the relevant skill at runtime instead of retaining every procedure in its core instructions.
Three elements define the described package. Instructions supply domain guidance and constraints to the agent’s context. Tool bindings identify dependencies such as APIs, Model Context Protocol servers, or local commands. A workflow supplies the task’s multi-step procedure or decision logic. The source’s concrete move is to evaluate such skill-equipped agents with Strands Evals and Amazon Bedrock AgentCore.
Operator implications
The operational unit suggested by this evidence is broader than a prompt. A skill joins behavioral guidance to external capabilities and procedural logic, so evaluation should treat those elements as one connected system. A well-written instruction set alone cannot establish how its bound tools or decision path will behave.
Runtime loading also creates a useful boundary for testing. Operators can examine the skill selected for a task, the dependencies it invokes, and the workflow it follows without assuming that all domain procedures are permanently present in the agent’s core context. That separation may make failures easier to localize, provided the evaluation covers each packaged element and their interaction.
Portability should be treated as conditional rather than universal. The source ties it specifically to compatible harnesses, which means an operator would still need to establish compatibility before relying on the same skill in another environment.
Limits and open questions
This is a single primary account and is not independently confirmed. The evidence pack does not provide evaluation results, success rates, comparative performance, failure cases, or measured operational outcomes. It also does not establish how compatibility is determined across harnesses, how runtime skill selection is governed, or how instruction, tool-binding, and workflow failures are distinguished in practice.
The supported conclusion is therefore structural: a skill can package specialized instructions, dependencies, and workflow logic for runtime use. Whether that structure improves reliability in a particular deployment remains unknown from the supplied evidence.