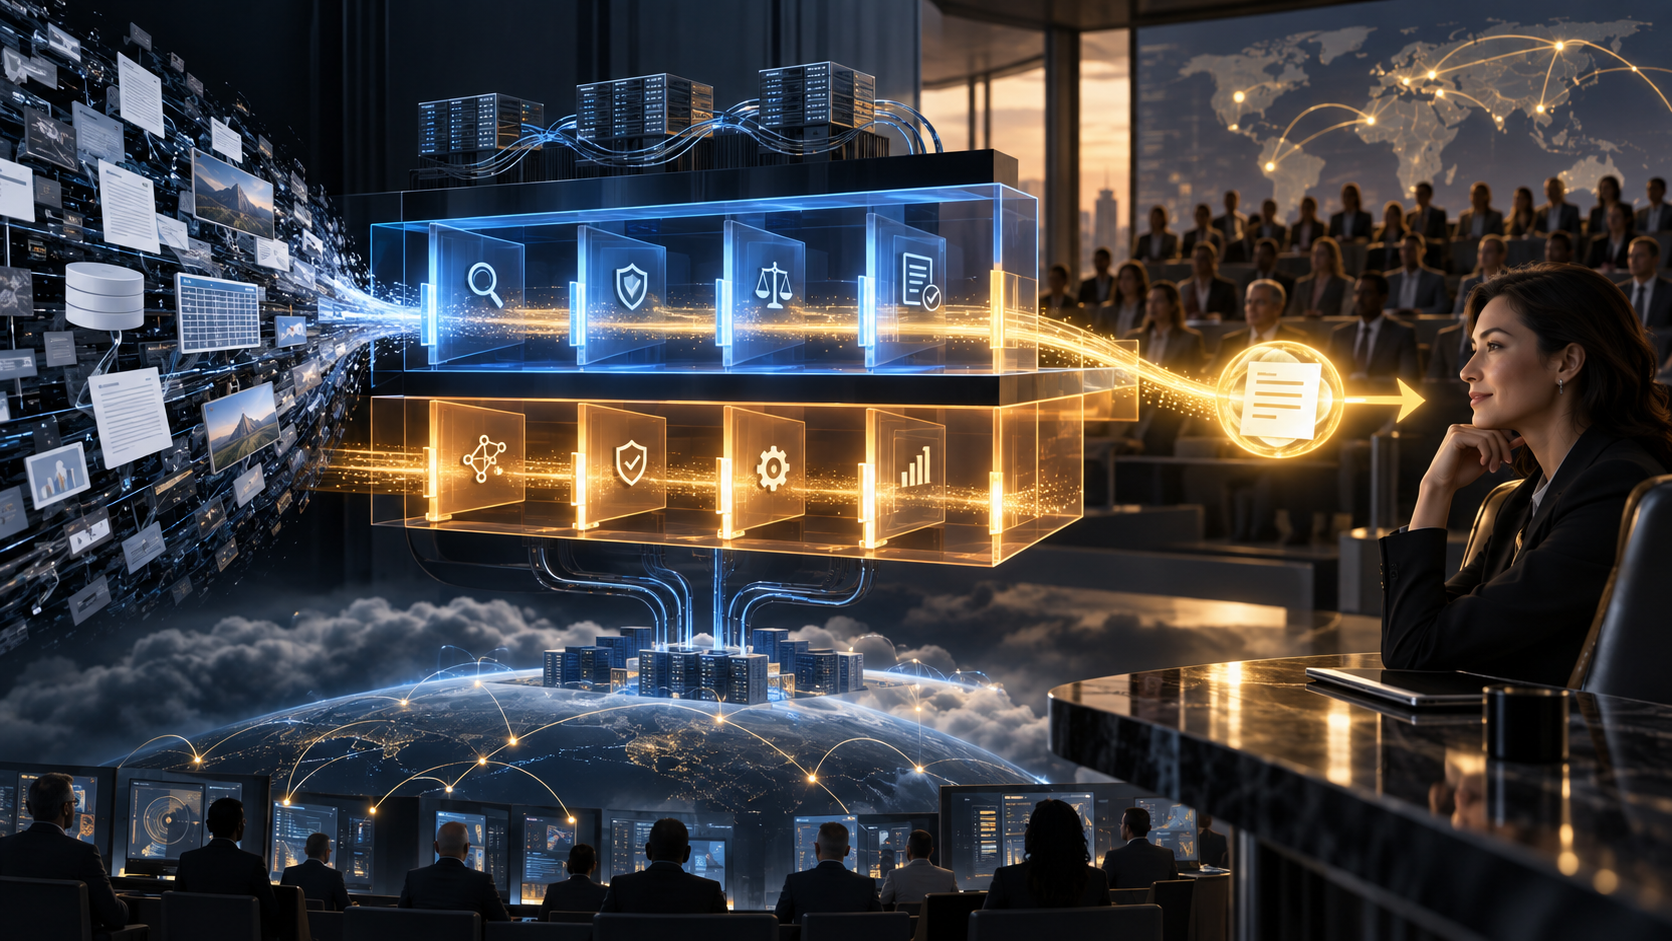
NarrateAI offers a useful operating premise for high-stakes LLM applications: model capability is only one part of production quality. When responses support executive business intelligence, accuracy and response speed both matter, and quality assurance must extend across the delivery path.
What the evidence says
AWS Machine Learning describes NarrateAI as serving more than 4,000 AWS executive leaders through a two-layer architecture built on Amazon Bedrock AgentCore. The primary account says the platform can support agents using any framework or model and identifies advanced quality-assurance mechanisms in the real-time layer as the post’s specific technical focus.
The source frames the operating risk in direct terms: an incorrect number or a slow answer presented to leadership can carry immediate professional consequences. It also states that a capable large language model cannot, by itself, guarantee correctness or timely delivery. Its proposed response is to build production-oriented quality assurance into the sequence from information retrieval through response delivery.
The stated audience is engineers and architects who already understand LLM APIs and streaming responses. That positioning makes this an implementation account rather than a general introduction to LLM systems.
Operator implications
Operator analysis: the central lesson is to treat answer quality as a property of the full application path. A model-centered review would leave retrieval, real-time handling, and delivery outside the quality boundary even though the source identifies that boundary as extending across all three.
For teams designing similar systems, the two-layer structure is less important as a pattern to copy than as a prompt to assign responsibility clearly. Operators can ask where each quality check occurs, which layer owns it, and whether the check remains active while a response is being delivered. The source’s emphasis on streaming responses also makes the real-time path a distinct area for architectural scrutiny.
The reported audience size raises the operational importance of consistency, but it does not itself demonstrate accuracy, speed, or reliability. Those outcomes would require measurements that are not included in the supplied account.
Limits and open questions
This is a single primary account and is not independently confirmed. It supports the description of NarrateAI’s intended architecture, audience, scale, and quality-assurance framing, but it does not provide independent evidence that the system achieves a particular level of quality.
The available material does not establish measured accuracy, latency, failure rates, evaluation methods, or how performance changes across frameworks or models. It also leaves the detailed responsibilities of both architectural layers unspecified here. Without those details, operators can use the account to identify a design principle—quality controls spanning retrieval through delivery—but cannot determine comparative performance, reproduce the implementation, or verify its reported operational effect.