What the evidence says
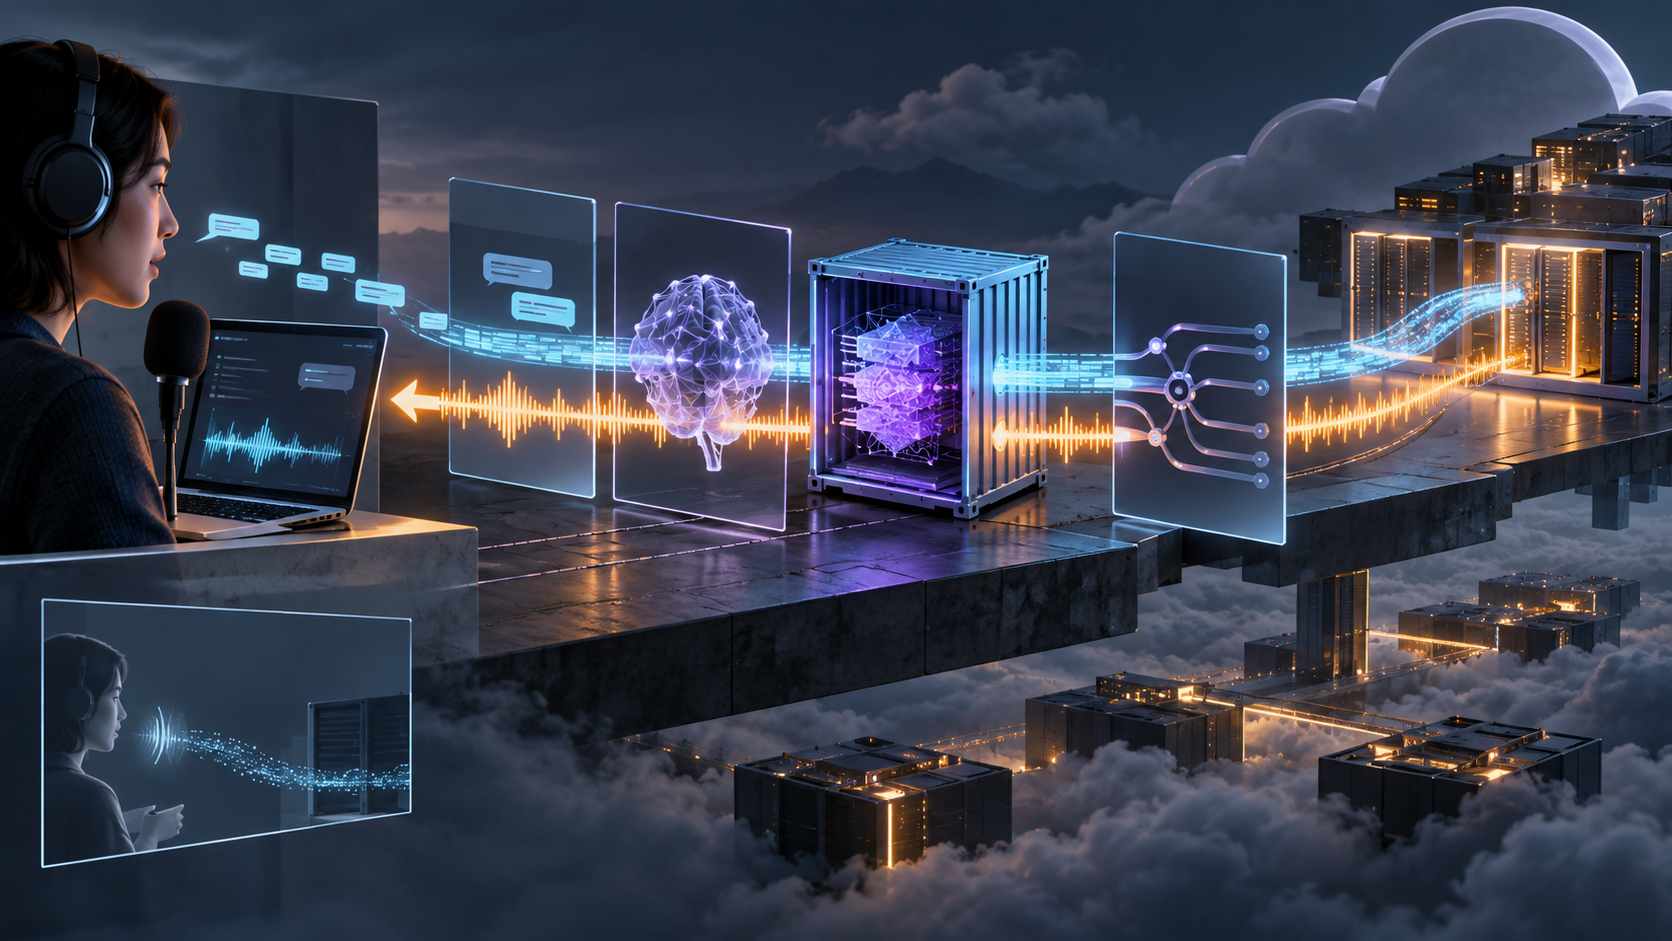
AWS Machine Learning reports a real-time voice workflow built around Qwen3-TTS, the AWS vLLM-Omni Deep Learning Container, and SageMaker AI. In the described setup, text enters and audio leaves through one persistent bidirectional connection. A Gradio application provides a way to try the workflow.
The container is described as packaging tracked vLLM-Omni releases in AWS images while adding routing middleware for SageMaker AI. The post also places this implementation within a broader series on specialized deep learning containers covering vLLM-Omni, WhisperX, and llama.cpp.
The account connects this work to an earlier post that demonstrated the input side of a voice pipeline. The present material focuses on streamed speech for real-time voice applications, making the persistent connection and containerized deployment path the central documented elements.
Operator implications
The following points are operational analysis, not reported outcomes. A single long-lived connection puts the end-to-end stream at the center of evaluation. Operators can therefore treat connection establishment, sustained exchange, interruption handling, and recovery as one test surface rather than evaluating text intake and audio delivery only as isolated steps.
The packaged container and added routing middleware also define practical boundaries for investigation. Teams can examine which behavior comes from the tracked vLLM-Omni release, which comes from the AWS image, and which is introduced by the SageMaker AI routing layer. That separation matters when reproducing a fault or deciding where observability should be placed.
The Gradio workflow can serve as an interaction point for examining the described path, but the source does not establish it as a production interface. Operators should distinguish successful workflow demonstration from evidence of readiness under their own traffic patterns, operating constraints, and failure conditions.
Because this is Part 1 of a series, the most defensible near-term move is to use the documented architecture as a testable reference: map the persistent connection, identify component boundaries, and define measurements before drawing conclusions about operational suitability.
Limits and open questions
This is a single primary account and is not independently confirmed. It documents components and a workflow, but the available evidence does not state measured latency, throughput, concurrency, resource use, cost, availability, or behavior under production load.
It also remains unknown how the connection behaves during interruption, how recovery is handled, what operating limits apply, and which deployment choices are required beyond the summarized workflow. No comparison with alternative architectures or containers is provided. Those gaps prevent conclusions about relative performance, reliability, scalability, or production outcomes.