What the evidence says
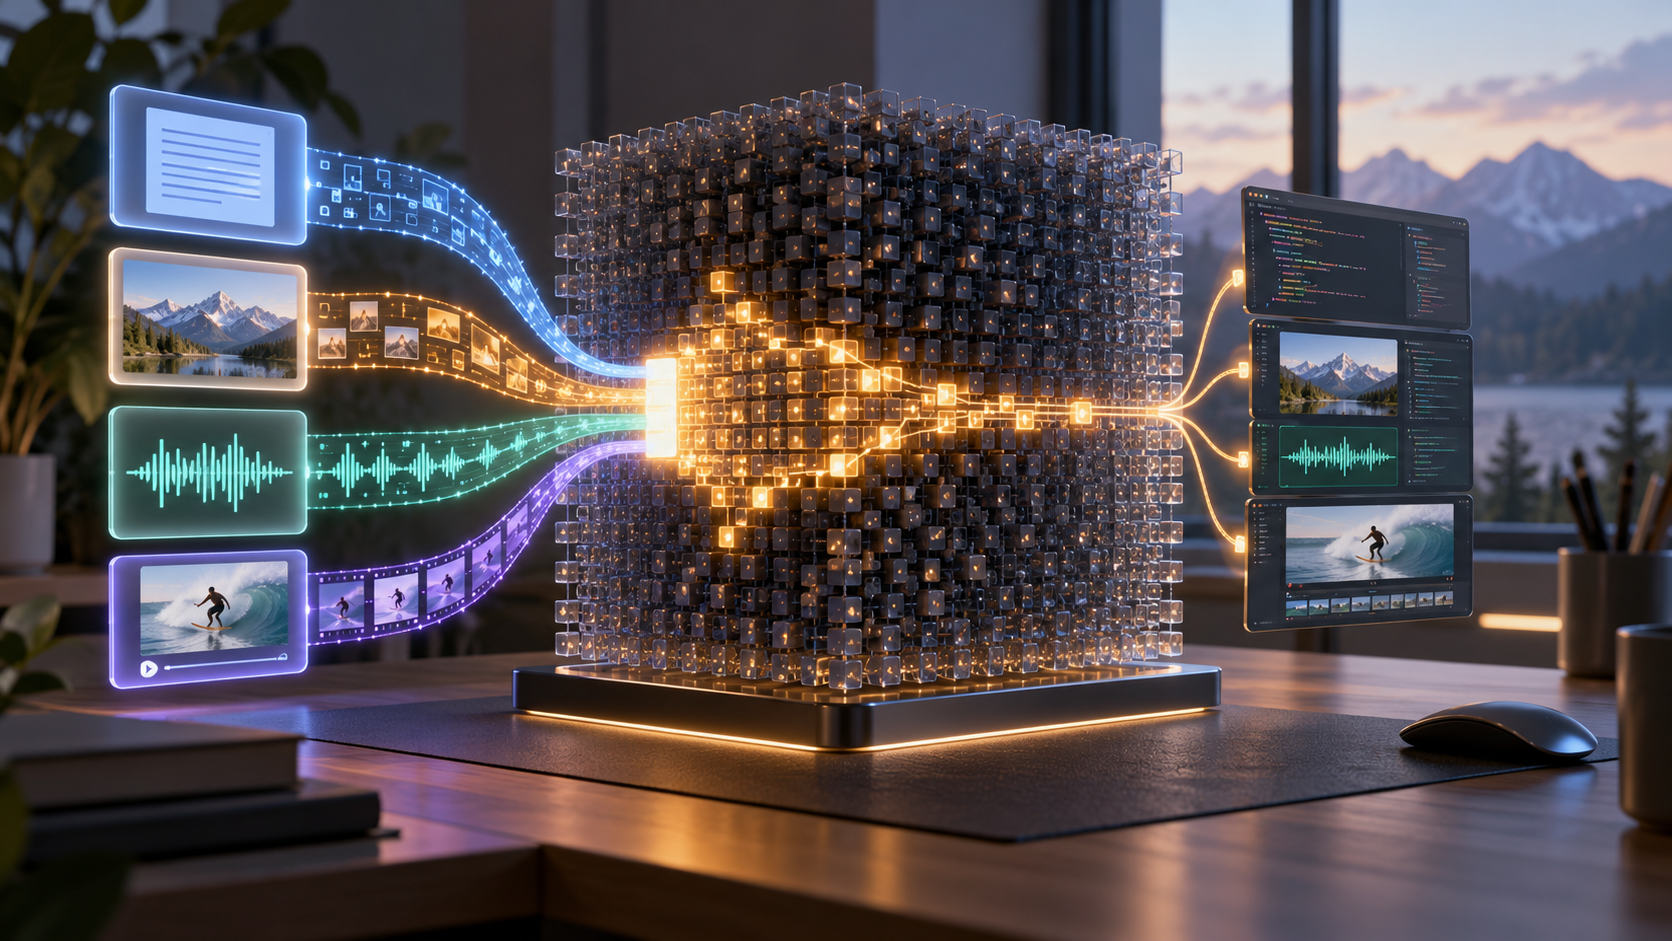
A primary post published by the Hugging Face Blog introduces Meta’s Muse Spark Open as a larger-scale successor to Muse Glimmer. The post describes it as a mixture-of-experts model spanning text, images, audio, and video, with approximately 816 billion total parameters, about 42 billion active per token, and a context window of up to one million tokens.
The primary account also relays Meta’s characterization of Muse Spark Open as the most capable US open-weight model to date. Meta describes the model as coding-optimized and says its training included developer workflows such as multi-file refactoring and long debugging sessions. Those capability statements and the frontier label are Meta’s claims, not independently established findings in the supplied evidence.
TechCrunch independently reports that Meta launched the open-weight model and that it runs on Macs. Its coverage confirms the disclosed 816-billion-parameter scale and one-million-token context window. It also reports that Meta claims superior performance over other popular open-weight models based on evaluation results released by the company.
Operator implications
For operators, the immediate significance is the combination of open weights, multimodal coverage, long context, and an explicit focus on coding workflows. That combination creates a clear evaluation target: determine whether the model’s claimed strengths translate to the specific multi-file refactors, extended debugging sessions, or mixed-media inputs relevant to an organization’s work.
The architecture also makes headline parameter count an incomplete operating signal. Meta’s disclosed figures distinguish approximately 816 billion total parameters from around 42 billion active per token. Any assessment should preserve that distinction and test the model under representative workloads rather than treating total scale alone as proof of usefulness.
TechCrunch notes that open-weight models can offer greater transparency and flexibility than closed alternatives and can be significantly more cost-efficient. Those are potential category-level advantages, not verified outcomes for every Muse Spark Open deployment. Operators would still need to establish whether the model’s practical performance, flexibility, and cost profile meet their own requirements.
Limits and open questions
The evidence does not provide independent benchmark replication, operator testing, deployment costs, latency measurements, memory requirements, hardware configurations, or reliability results. It also does not establish how Mac performance varies across devices or workloads.
The supplied reporting verifies that the launch and Meta’s claims were publicly described by two distinct sources, but it does not independently prove Meta’s comparative-performance claim. The central open question is therefore practical: whether Muse Spark Open’s disclosed scale, selective activation, long context, and workflow-oriented training produce repeatable advantages outside Meta’s evaluations.